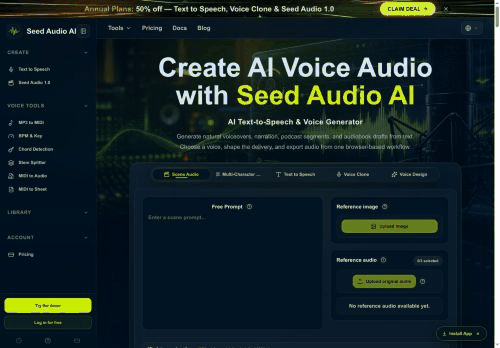
 Seed Audio AI: Next-Generation Browser-Native Speech Synthesis & Integrated Music Production Hub
Created 05 Oct 2026
Seed Audio AI represents a breakthrough in browser-based audio generation and multimedia creative workflows by uniting high-fidelity expressive Text-to-Speech (TTS), voice cloning, and generative multi-modal audio production with a full suite of musician-grade utility tools. Traditional voiceover, commercial ad production, podcast assembly, and audiobook narration suffer from severe structural friction: expensive physical studio bookings, tedious cast coordination, slow revision turnaround cycles, and fragmented toolchains that force creators to switch back and forth between disparate software applications. Seed Audio AI completely redefines this paradigm by introducing an all-in-one browser environment where digital creators, marketing agencies, podcasters, game developers, and multimedia producers can convert raw scripts into human-like audio drafts in seconds, fine-tune emotional nuances and pacing, and seamlessly blend spoken narration with musical elements. Central to the platform is Seed Audio 1.0, an innovative multi-prompt generative engine capable of orchestrating spoken dialogue, ambient audio textures, background music (BGM), and sound effects (SFX) concurrently from text prompts, reference audio, or image inputs. Supplementing this core generative capability is a robust suite of six free client-side audio utilities—including MP3-to-MIDI transcription, real-time BPM and key detection, chord progression mapping, AI stem separation, MIDI rendering, and sheet music generation. By embedding foundational music theory utilities directly alongside advanced voice cloning and rights-aware TTS workflows, Seed Audio AI bridges the historical divide between speech generation and musical audio design. This unified ecosystem significantly decreases time-to-market for digital media, lowers overall production costs by up to 80 percent, ensures strict brand voice continuity across international marketing campaigns, and establishes an accessible, scalable creative workspace tailored to both solopreneurs and enterprise marketing operations.
Industries
Get your First 100 Clicks in ONE MONTH
FREE with AI CMO (Saving £500+)
Save over £428 in ad value compared to paid traffic.Faster and Higher ROI than traditional SEO services (3–6 months) and lower cost (£500–£2000/month).
SEO Market Overview (Organic Search)
Global AI Audio and Speech Synthesis SoftwareThe synthetic speech and browser-based audio production market features intense paid search competition and elevated cost-per-click values. High commercial intent is driven by content creators, marketing agencies, and media companies seeking automated voiceover and audio production toolchains with rapid deployment cycles.
0.0%
AI VisibilityGEO / AI Visibility Overview
How visible your brand is inside AI-generated answers
Unlock More Content Ideas
Create an account or log in to explore exclusive blog topics, SEO strategies, and GEO-targeted content generated by AI CMO Maggie
[ Tailored for your brand's next growth leap. ]
Maggie Studies the Tracks Before the Journey Begins.
She learns every detail of your business through deep market research.
Target Problem
The contemporary digital audio landscape is plagued by fragmentation and operational friction. Traditional voice production requires booking recording studios, coordinating talent schedules, managing physical microphone acoustic variations, and enduring costly review cycles whenever a minor script alteration occurs. For independent creators, advertising agencies, and corporate content teams, these bottlenecks create unacceptable delays and inflated budgets that limit their capacity to produce high-volume content across global digital channels. Simultaneously, creators are burdened by fragmented utility toolchains. A standard production workflow frequently forces sound designers and video editors to juggle separate standalone applications for text-to-speech narration, stem separation, musical key analysis, tempo matching, and MIDI transcription. This constant switching between disparate platforms disrupts creative momentum, introduces formatting incompatibilities, and requires multiple expensive recurring SaaS subscriptions. Seed Audio AI decisively solves these dual problems by delivering a single, frictionless browser-based platform. By coupling natural, controllable voice generation and ethical cloning with an essential suite of audio conversion and analysis utilities, Seed Audio AI streamlines the entire journey from text script to final audio mix. Teams can now draft, localise, refine, and orchestrate high-quality spoken audio and accompanying musical beds without ever leaving the browser interface.
Target Regions
Target Audience
Independent Content Creators & Video Producers
YouTubers, TikTok creators, and social video editors seeking rapid, studio-grade voiceovers, automated background music alignment, and stem extraction without investing in dedicated studio gear.
Digital Marketing & Advertising Agencies
Creative agencies requiring high-velocity voiceover prototypes, localized commercial ad variants, and reusable vocal styles to match specific brand personas across omni-channel campaigns.
Audiobook Publishers & Indie Authors
Authors and publishers seeking to convert manuscripts into paced, multi-character narration drafts with consistent tonal delivery and chapter-by-chapter safety auditing prior to publication.
Podcasters & Media Broadcasters
Audio hosts and producers drafting dynamic intros, host-read sponsorships, segment transitions, and ambient beds with repeatable delivery settings.
Indie Game Developers & Animators
Game studios drafting character dialogue, interactive voice prompts, and sound effects via text prompts and reference audio to rapidly prototype gameplay scenes.
Market Research
The global synthetic media and AI audio market is undergoing exponential growth driven by the surging volume of digital video, podcasting, interactive gaming, and localized advertising. According to industry analyses by Grand View Research and MarketsandMarkets, the global text-to-speech market was valued at approximately USD 3.4 billion in 2023 and is projected to expand at a compound annual growth rate (CAGR) of over 25.8% through 2030, exceeding USD 16.5 billion. Simultaneously, the broader generative AI in media and entertainment market is anticipated to cross USD 31.9 billion by 2032, propelled by innovations in neural audio codecs, multi-modal diffusion transformers, and real-time voice synthesis. The target regions—led by North America and Europe, with rapid acceleration across Asia-Pacific—represent over 70% of the total addressable market (TAM). In North America, high digital marketing expenditure and a massive creator economy ecosystem (comprising over 50 million content creators in the United States alone) fuel adoption. Content teams increasingly demand frictionless, self-service audio platforms that bypass legacy hardware dependencies. Furthermore, the global music technology and stem separation software sector adds an estimated USD 1.8 billion addressable market, as sampling, remixing, and music transcription transition toward AI-driven browser micro-tools. Key drivers accelerating this transition include the decentralization of digital media creation, shortening ad development cycles, the proliferation of short-form video (TikTok, Instagram Reels, YouTube Shorts), and the necessity of multilingual content localization. While incumbent vendors concentrate strictly on voice generation or DAW plug-in distribution, creators increasingly favor lightweight, unified platforms that bridge the gap between voiceover drafting and musical utility processing. Consequently, Seed Audio AI is positioned in an attractive blue-ocean intersection, capturing value across both speech synthesis and browser-based musical utility segments.
The modern digital content landscape is characterized by an insatiable demand for rapid audio production across video, interactive gaming, educational broadcasting, and digital commerce. Historically, high-fidelity sound engineering has required prohibitive capital outlays, complex digital audio workstations, and extensive technical expertise. Seed Audio AI establishes a new operating benchmark by abstracting technical complexity away into an intuitive web browser workspace. By combining sophisticated neural text-to-speech modeling with utility-level music manipulation tools, the platform dismantles traditional barriers between voice talent, audio engineers, and content creators. The foundational architecture of Seed Audio AI rests on two interconnected technical pillars: the high-fidelity neural voice synthesis engine and the multi-modal Seed Audio 1.0 framework. Traditional text-to-speech systems frequently fail when deployed in narrative or high-energy contexts due to monotonic cadences, unnatural pause placement, and flat dynamic curves. Seed Audio AI overcomes this limitation by implementing nuanced delivery controls that allow creators to modulate pacing, emotional intensity, syllabic stress, and vocal timber. Whether producing an urgent commercial radio spot, an intimate serialized audiobook chapter, or a polished podcast sponsorship read, users maintain granular control over the expressive trajectory of their voiceovers. The platform's multi-modal extension, Seed Audio 1.0, further transforms creative workflows by pioneering multi-track generative synthesis. Rather than requiring users to source background music from stock libraries and search sound effect databases for matching Foley, Seed Audio 1.0 allows creators to supply a single composite prompt—optionally accompanied by reference audio or a visual mood board—to generate spoken dialogue, synchronized background music, and contextual Foley sounds in a unified pass. This unified audio drafting capability accelerates early-stage pre-production for indie game developers, animators, and commercial video editors, who can audition comprehensive soundscapes within minutes of script finalization. Equally transformative is Seed Audio AI's decision to co-locate six essential musical utilities within the core voiceover workspace. Producers frequently encounter audio friction when attempting to align spoken voiceovers with musical tracks. By integrating browser-native stem splitting, key detection, BPM extraction, and chord recognition directly alongside the voice generator, users can drop an instrumental backing track into the platform, instantly analyze its tempo and musical key, separate lead elements from rhythm sections, and adjust the pacing and pitch of the generated voiceover to ensure harmonic coherence. For musicians and beatmakers, the MP3-to-MIDI, MIDI-to-sheet, and audio conversion tools provide additional utility, establishing Seed Audio AI as a versatile daily hub rather than a single-purpose voice generation tool. From a market adoption and go-to-market perspective, Seed Audio AI's freemium utility strategy serves as a highly efficient customer acquisition flywheel. By offering powerful tools like stem separation, chord mapping, and MIDI conversion for free in the browser without mandatory software installation, the platform attracts thousands of organic creators, remixers, and musicians daily. Once inside the ecosystem, these users naturally discover the advanced voice cloning, multi-modal synthesis, and premium text-to-speech credit tiers. As digital content production continues its unstoppable shift toward automated, browser-first collaboration, Seed Audio AI is exceptionally well-positioned to expand its footprint and redefine modern creative audio workflows.
Maggie Maps Your Rivals Before Full Steam Ahead.
She benchmarks your brand against competitors to plot a smarter route.
Products & Services
Browser-Based AI Text-to-Speech Workspace
An intuitive in-browser text-to-speech engine that converts scripts into studio-quality voice drafts with fine-grained controls for pacing, emotion, tone, and character delivery.
Seed Audio 1.0 Generative Audio Engine
An integrated multi-modal audio synthesizer that generates dialogue, background music (BGM), sound effects (SFX), and ambient room sound from text, reference audio, or image cues in a single unified prompt.
Permission-Aware Voice Cloning & Reusable Profiles
High-fidelity digital voice replication system with strict permission boundaries and reusable profile settings designed to preserve brand consistency across global marketing campaigns and episodic media.
AI Stem Splitter
A deep-learning separation utility that isolates vocal tracks, drums, basslines, and instrumental accompaniment from mixed audio files for remixing, sampling, and post-production.
MP3 to MIDI Converter & Chord Detector
Browser-native transcription tools that extract melodic note arrangements into editable standard MIDI files and map chord progressions along a visual interactive timeline.
BPM & Musical Key Analyzer
Instant algorithmic tempo (BPM) and musical scale/key detection tool designed for sampling, mashups, playlist curation, and seamless voiceover-to-music synchronization.
MIDI to Sheet Music & Multi-Format Audio Hub
Notation converter and rendering hub that transforms MIDI inputs into printable sheet music, MusicXML files, or rendered high-fidelity audio formats including MP3, WAV, and FLAC.
Unique Selling Points
SWOT Analysis
Strength
Comprehensive integration of speech synthesis with six specialized music production utilities in a fast, browser-native interface, backed by multi-modal generation capabilities.
Weakness
Brand awareness is still developing compared to legacy synthetic voice players; high compute costs associated with running real-time multi-modal audio diffusion models.
Opportunity
Rapidly growing demand for localized multimedia content, corporate training narration, generative AI game audio, and automated audiobook self-publishing ecosystems worldwide.
Threat
Aggressive feature expansion by established audio giants (such as ElevenLabs and Adobe) and evolving global regulatory policies regarding voice rights and synthetic media watermarking.
Market Competitors
 ElevenLabs
Market-leading synthetic voice platform recognized for hyper-realistic voice cloning, multilingual speech synthesis, and sound effect generation, though focused primarily on speech rather than integrated music analysis utilities.
Visit Site Murf AI
Cloud-based AI voiceover studio tailored for corporate e-learning, product explainers, and presentation voice tracks, featuring a rich library of licensed voices and slide synchronization.
Visit Site PlayHT
AI voice generator and voice cloning platform offering conversational speech models and low-latency APIs for podcasts, streaming avatars, and character voices.
Visit Site Speechify
Leading text-to-speech reader and voice generation ecosystem primarily focused on consumer accessibility, document narration, and student productivity reading tools.
Visit Site WellSaid Labs
Enterprise-grade synthetic speech platform tailored for digital training modules and marketing communications, emphasizing high compliance and human-vetted voice actors.
Visit Site Lovo AI (Genny)
Comprehensive creative suite integrating AI voice generation, video editing, subtitle generation, and generative AI art for creative content creators.
Visit Site Descript
All-in-one audio and video editing platform centered on text-based script editing, Overdub synthetic voice generation, filler word removal, and automated transcription.
Visit Site Resemble AI
High-fidelity AI voice generator specializing in enterprise voice cloning, real-time latency synthesis, deepfake voice detection, and audio watermarking.
Visit Site Moises.ai
Popular AI-powered musician platform providing stem separation, pitch shifting, chord transcription, and tempo detection, catering primarily to musicians and audio engineers.
Visit Site Suno AI
Generative musical audio platform generating full-length songs with vocals and instrumentation from text prompts, focused on music entertainment rather than commercial voice drafting.
Visit SiteLaunch Effortless Blogging with Maggie
No more blank pages. Maggie runs your blog with vibe-rich, SEO-tuned, GEO-smart content — built to be loved by search engines and surfaced by AI.
Free Tools
AI Visibility CheckerAI Ideas BrainstormingAI Startup Trend AnalysisAI Project ManagementWordPress CheckerAI Co-Founders
Roadmap
All rights reserved by AI Marketing OS Ltd. Designed & Developed by TOPY.AI .